

Problem Statement
The pull request concept (PR) hasn’t changed shape since GitHub introduced it in 2008: a diff, a thread, an approve button. What’s changed is who’s on either side of it.
Increasingly, it’s about agents proposing code changes, agents commenting on it, and humans wondering what their job in the middle is supposed to be now.
The optimistic case
Martin Monperrus’ The End of Code Review argues that LLM-based coding agents have crossed a threshold where “every stated goal of code review can be served by agents at lower cost and higher throughput,” and that routing AI-generated code through human reviewers is a mismatched integration model, too slow for agent output, too shallow to catch what matters.
It’s a deliberately blunt thesis, but it names a real pressure: review queues are becoming the bottleneck, not code generation.
What the data actually shows
Automated review isn’t free triage.
An ICSE 2025 study, Cihan et al., “Automated Code Review In Practice”, tracked 4,335 pull requests across ten projects. Comments got resolved most of the time, a real signal, but closure time went up, with only minor quality gains and a steady stream of faulty or irrelevant ones. Right now, automated review is considered a second, chatty reviewer
The agents aren’t ready to grade their own homework either. Zhang et al.’s c-CRAB benchmark tested PR-agent, Devin, Claude Code, and Codex against real human-reviewed pull requests, finding they solve only about 40% of tasks, focusing on different things than human reviewers do.
On the authoring side, SWE-Bench Pro raises the bar to long-horizon, multi-file tasks, resisting the contamination that made earlier numbers look rosier than reality.

Agents creating and reviewing PRs?
So what does “review” even mean when agents write the code?
Duma et al., “These Aren’t the Reviews You’re Looking For” mined the AIDev dataset and found most AI-generated PRs receive no review at all, and when they do, the reviewer is often another agent, not a human.
When they do, it’s often by another agent. Humans mostly steer the agent rather than comment line by line.
Pair that with Huang et al., “More Code, Less Reuse”: AI-generated PRs carry more redundant code, yet reviewers feel better about them. That’s how technical debt sneaks in.
So worse code, better vibes.
The Nature of the PR
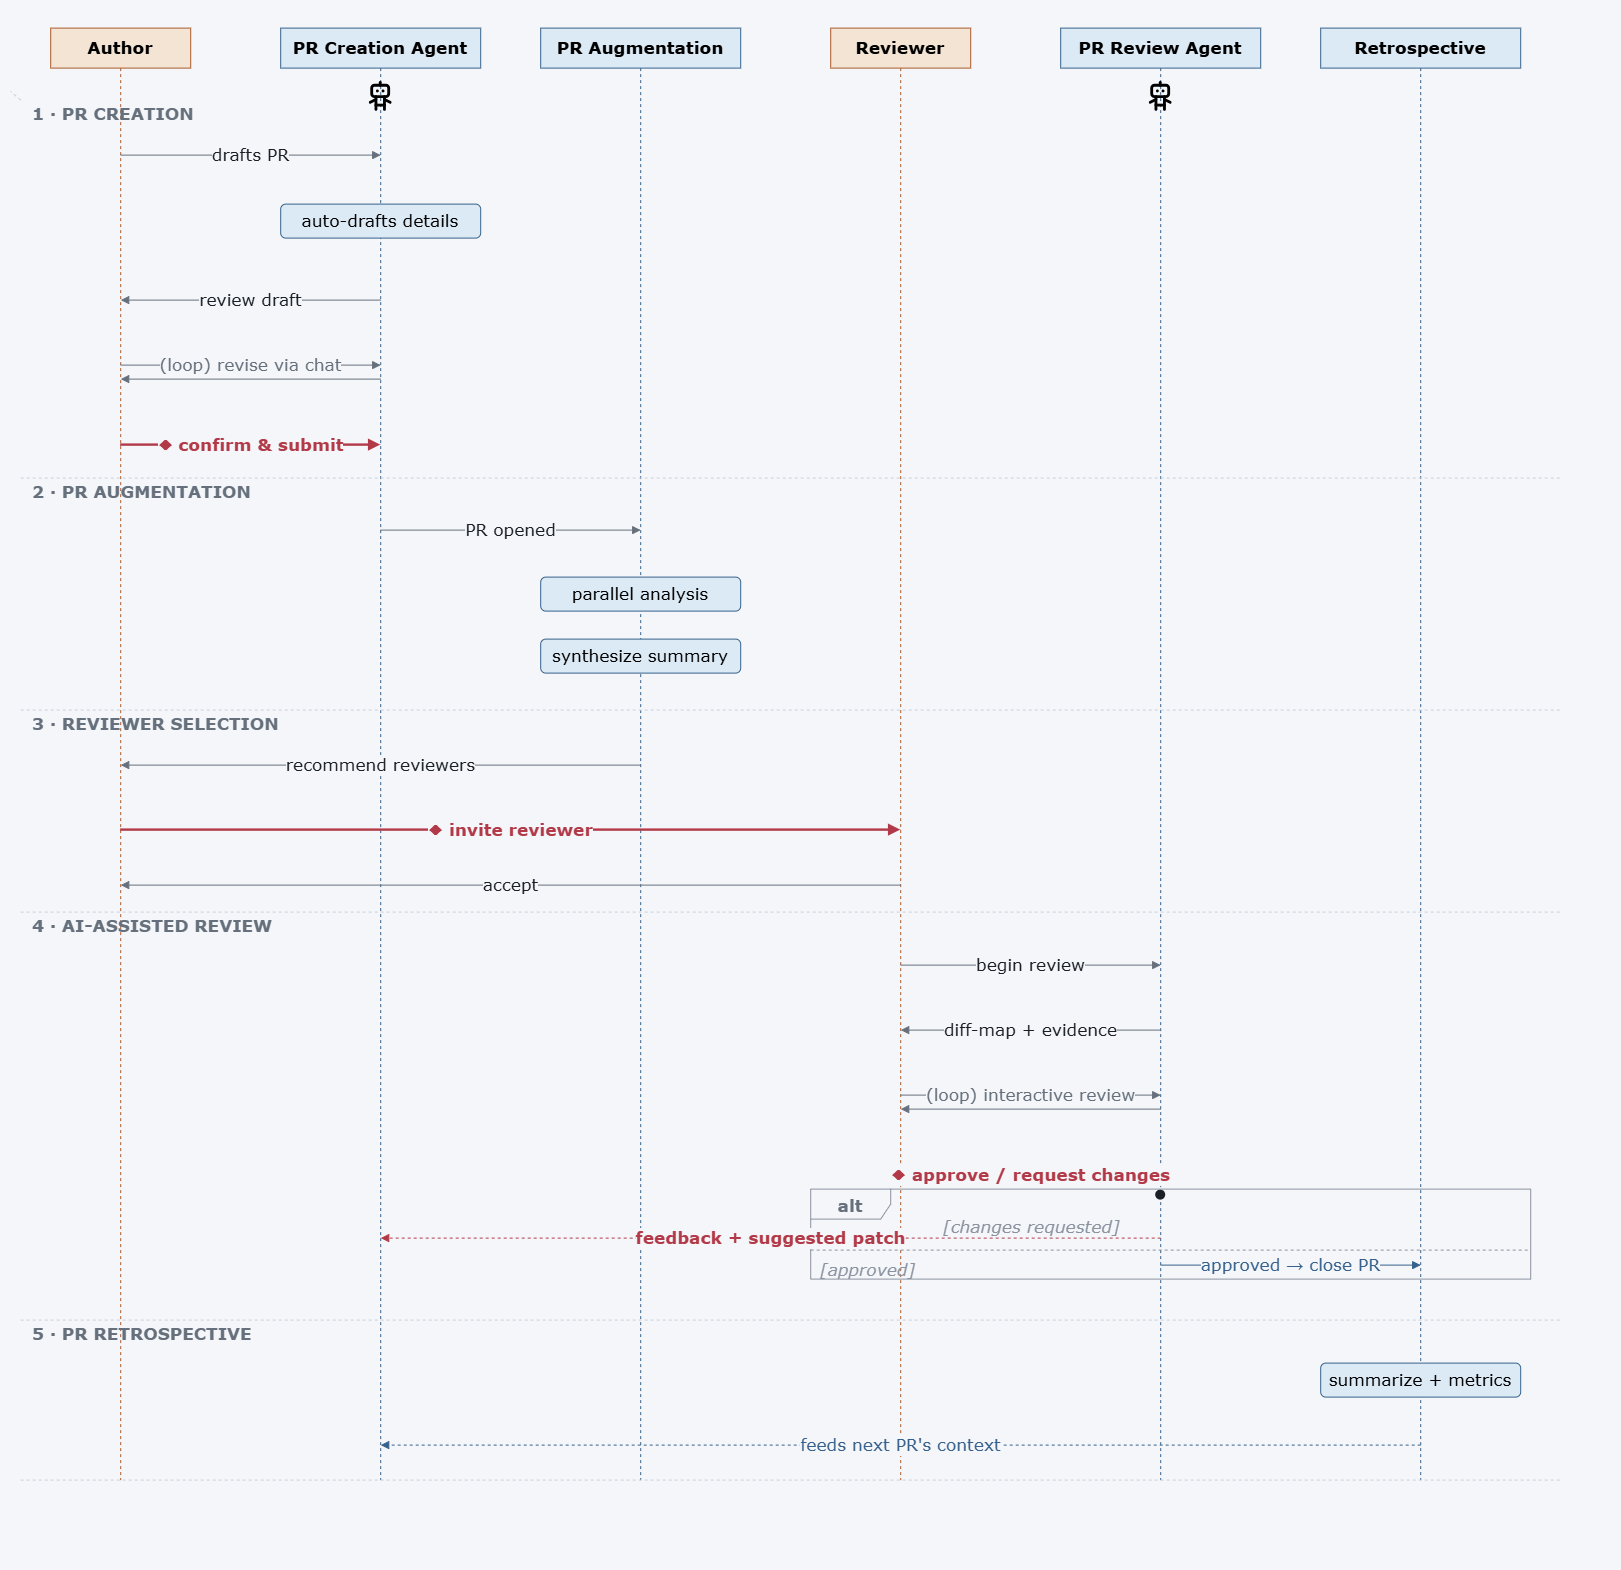
A very interesting and pragmatic approach is Kamalı et al., “Rethinking Code Review in the Age of AI”: restructure the review lifecycle into five stages (creation, augmentation, reviewer selection, AI-assisted review, retrospective), with humans repositioned as “supervisory operators of agents,” retained at decision points that need judgment, not every diff line.
That framing beats the “review is dead” and “nothing has changed” narratives.
The research points to a transition, not a singularity:
The unit of trust is moving. From “did a human read every line” to “did the right gate catch the right class of problem,” with tests, verification, and human judgment applied selectively, not uniformly.
The redundancy and sentiment-gap findings are the near-term risk, not benchmark scores. Teams that let agent-generated PRs sail through because they look clean are accumulating the debt Huang et al. describe.
Review capacity, not code generation, is the constraint to plan around. If closure time is already growing, adding more agent-authored PRs makes the queue worse before an agentic pipeline helps.
The reviewer role bifurcates. Routine, verifiable work goes almost entirely to agents; humans concentrate on architecture, intent, and the decisions that need a name attached to them.
The highest-leverage human work moves upstream, to requirements. Hamblin et al., SpecBench tested LLM agents on real RFC processes from Kubernetes, React, Rust, TVM, and vLLM, spotting omissions and bad assumptions before code is written. Even the strongest model tested, GPT-5.4, hit only 44.4% accuracy, far below its code-generation scores. If agents judge what should be built worse than whether it’s correct, reviewing requirements protects best against a bad diff.
A flawed spec produces a technically clean PR that still solves the wrong problem, and no amount of downstream code review catches that.
The industry is already building this
Several companies have shipped what those papers point at.
GitHub reports Copilot code review has processed over 60 million reviews, now touching more than one in five on GitHub (Griffiths, 2026). Its guidance echoes the findings above: agent code “appears clean but harbors hidden technical debt,” so the fix is procedural, an implementation plan and new tests required, automated review treated as a filter, not a replacement for judgment.
Uber’s uReview runs three specialized reviewers plus a validation stage against roughly 90% of its ~65,000 weekly diffs (Uber, 2025). Its comments get addressed in the same changeset 65% of the time, against 51% for humans, beating the reviewers it’s supposedly a lesser substitute for.
Stripe’s minions show full agent authorship in production: over 1,300 pull requests a week are, in Stripe’s words, “human-reviewed” but contain “no human-written code” (Stripe, 2026), on a payments platform moving over a trillion dollars a year.
Google’s 2025 DORA report is the reality check: 90% of developers use AI at work, but only about a quarter trust its output “a lot,” and AI amplifies a team’s existing practices rather than fixing them (Google Cloud, 2025).
AI doesn’t fix a team, it amplifies what’s already there.
– Google Cloud team
The manufacturing precedent
Software isn’t the first discipline to hit this problem.
Manufacturing solved a structurally similar one decades ago:
How do you assure quality on a line producing faster than any human can inspect? The answer was never “look at every single part.”
Acceptable Quality Limit sampling (from ISO 2859) accepts or rejects a whole batch based on the defect rate in a sample, not because any unit matters less, but because 100% inspection stops paying for itself once a process is stable.
Statistical process control goes further, watching the process itself, so control charts flag drift before a defective part is even produced. Full inspection survives only where a miss is catastrophic and unrecoverable, like aerospace fasteners or implantable medical devices; everywhere else, trust sits in the process, with a human stepping in only when something drifts out of tolerance.
That maps onto Kamalı et al.’s framework above: agent-based review as automated gauging on every PR, full manual inspection reserved for genuinely catastrophic diffs (a security boundary, a data migration, a public API contract), not applied out of habit to every line. Insisting on 100% human eyeballs for AI-authored PRs looks like insisting on calipers for every bolt off a line already in statistical control.
The pattern isn’t unique to manufacturing. Auditors sample against a materiality threshold rather than tying out every transaction, scaled to risk, not volume. Radiology screening sits closer to the aerospace end: double-reading survives because a missed cancer is unrecoverable, but AI increasingly triages which scans need that second set of eyes rather than reading them all itself.
Routine volume gets an automated or statistical gate, human attention gets rationed by risk, and full manual inspection survives only where a miss can’t be recovered downstream.
Is text diff even the right format?
Everything above assumes the artifact under review stays fixed: a diff plus a paragraph of prose. That’s worth questioning.
The unified diff came before the pull request, and it was made for a human reading line by line in a terminal. The description we stick on top is just a habit, not a design. Nothing ties the prose to the actual changes, so every reviewer, person or agent, is left guessing at the intent all over again.
If requirements are where the leverage has moved, the diff and the requirement it satisfies should be linked structurally: a PR as a set of (requirement, change) pairs, where anything unattached is a flag by construction, the way DO-178C and ISO 26262 already require in safety-critical software. An agent generating a diff already has the requirement in context, so making that link explicit costs almost nothing. Schlathölter’s ReqToCode makes traceability a build-checked property of the code itself, and Akhavan et al.’s LinkAnchor recovers issue-to-commit links autonomously, since only 42.2% are correctly linked today. Neither is a gatekeeper agent, but together they’re most of the way there.
Abenhaim’s account of dismantling a core architectural invariant wires that idea all the way through: a 717,725-line production app, 189 files, with no human code review. The agent audited its own formal spec against the existing code for 14 cycles, implemented, then audited the implementation against the frozen spec for 17 more, catching 201 defects before a human ever ran the program. Three days, $2,430.
Zietsman’s “The Specification as Quality Gate” shows why this isn't reckless. Without an executable spec, the AI reviewer and the AI author learned from the same training data, so the review just checks the code against itself, not against intent. His fix matches Abenhaim's protocol: spec first, deterministic checks second, and AI review only for what's left. The AI gets a small, defined target instead of everything.
Philipp’s Ada/SPARK study shows the best case. Formal proof is stricter than any plain-English spec, and it got through 49,280 proof obligations on crypto and TLS/IKEv2 code at 20 to 40 times less supervision than verifying by hand. Even so, the prover missed bugs that human reviewers caught, because "what an agent can be trusted to establish is bounded by the strength of its feedback."
“No code review” turns out to mean no human reading the diff line by line, not no verification.
Beyond plain text: other pull request formats
Pairing requirements with changes fixes the prose. The diff is still a leftover too: - and + lines tied to files and line numbers, made for someone in a terminal. Delta makes it nicer to read but doesn't change what it shows. What comes next does.
Structural diffs. A line diff can't tell a rename or a reformat apart from a real change in logic. It all looks like the same noise. Tools like
difftasticcompare the syntax tree instead of the lines. An agent already has the AST in hand, so why throw it away?Executable claims, not just code. A diff tells you what changed, not what’s supposed to be true now. If the change comes with an assertion a machine can check, like a property test or an invariant, review becomes one question: “does this claim hold?” Agents are already much better at that than at open-ended judgment calls.
Impact-graph views. A three-line change to a shared utility and a three-line change to a leaf component look the same in a diff. Their blast radius is very different. Rendering the dependency graph turns “small diff” into a real risk measurement. Graphite’s take on full-repo vs. diff context makes the same case from the review side: diff-only misses cross-module impacts, so their Diamond reviewer prunes by dependency instead of the whole repo.
A different unit of change. Commits aren't sacred. Google’s Jujutsu treats the working copy itself as a commit, cutting staging and rebase, and Meta’s Sapling builds stacked, reviewable commits by default. If version control’s unit can be rethought, so can review’s.
None of this kills the diff.
Someone will always want the line-by-line view. But the lesson is the same across all of them: an agent can hand you the why, the proof, and the blast radius in structured form, almost for free. A terminal-era format just wasn't built to carry that.
Where this leaves us
The PR isn’t going anywhere, but the diff shouldn’t be the thing we review anymore.
We read code line by line because it was the only tool we had, not because anyone cares that line 47 changed. What we care about is whether the system still does its job. Abenhaim, Zietsman, and Philipp all land in the same place: check code against what it’s supposed to do, not how it looks on a screen. That’s not less review. It’s what diff-reading was always standing in for.
So this isn’t “no code review.” It’s verification moved off human eyes and onto the requirement. A change with no requirement behind it is a defect, read or not. A change that matches its requirement isn’t safer because someone also skimmed it.
The bet worth making now:
Wire requirement-to-code traceability into the merge path.
Fail the build on unlinked changes.
Save human reading for what specs can’t cover: security boundaries, data migrations, the truly fuzzy stuff.
The tools are already here. What’s missing is the willingness to admit “a human read it” doesn’t tell us much.
What does? Requirements. And that’s what I’ll keep talking about in the next posts.